EmbeddingGemma 2 brings local text, image and audio search together
Google's new embedding model lets developers compare different kinds of media in one search system. It is a building block for applications, rather than a complete search product.
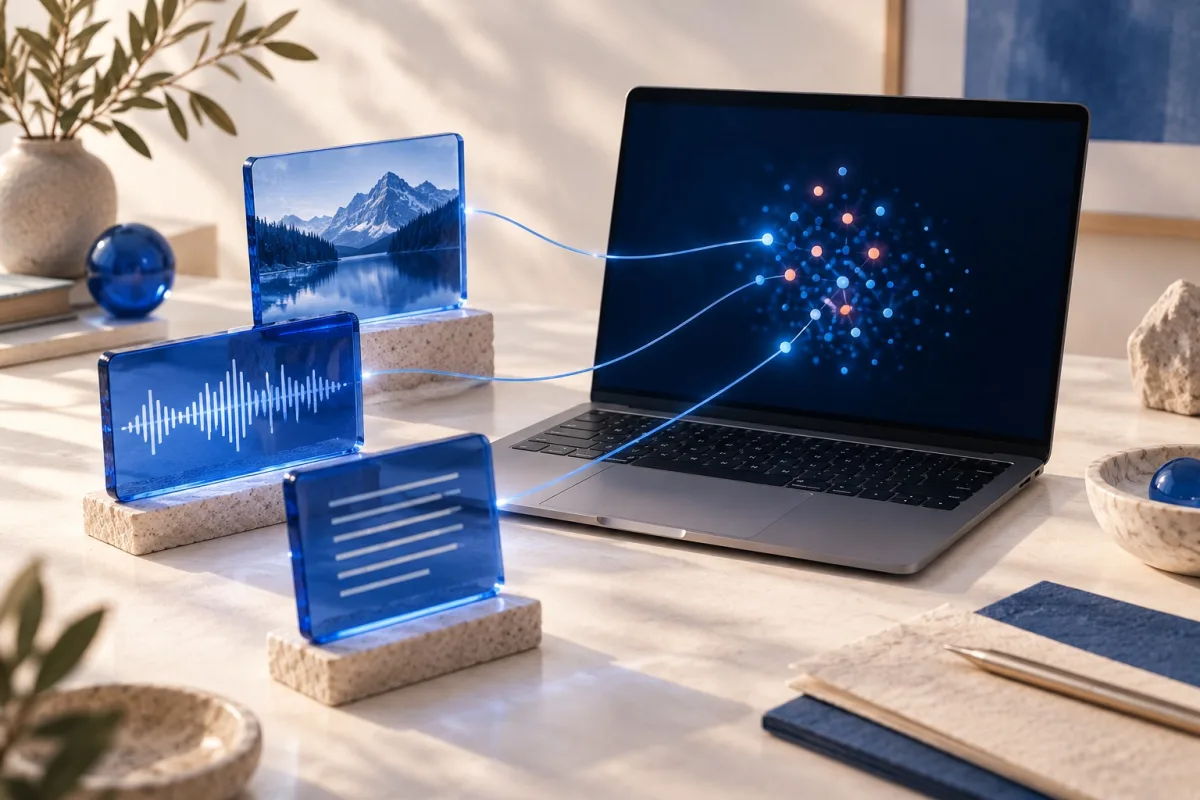
Search across different media types.
Load only the components you need.
Measure retrieval and memory on the intended device.
The short answer
Google announced EmbeddingGemma 2 on October 6. The model represents different types of content as comparable numerical vectors, making it possible to match a written query against images or recordings. The release is aimed at developers building search into their own software.
Finding a scene without knowing its filename
Consider a small game studio looking for material for a rainy forest scene. A shared search system could suggest concept art, sound effects and production notes together. This is our proposed use case, not a workflow we have tested. The useful question would be whether the results help an artist find the right material faster than browsing folders. Similarity alone cannot settle that question.
Choose the components your archive needs
The developer guide describes a modular setup: text and code use 270 million parameters; the complete model with vision and audio has 740 million. Its examples distinguish query prompts from document prompts. Developers can also shorten stored vectors, but should measure what that does to search quality.
Read the small memory figure carefully
Google's roughly 191 MB figure refers to quantized text-only weights on a Pixel 11 Pro. The announcement gives roughly 567 MB of active RAM for the full multimodal model. Neither figure promises that an entire application, including its files and index, will fit into that amount of memory. The model card lists an Apache 2.0 licence. Building and maintaining an application still requires resources.
A useful first experiment
We would start with a small collection cleared for use and ten actual questions from the people who will search it. Record the expected useful files before running the experiment. Then compare retrieval results with those expectations and measure response time and memory on the intended device. Include at least one question that the collection cannot answer. This proposed evaluation would expose practical problems before the team spends time indexing a much larger archive. It is not a report of a completed benchmark.
Retrieval still needs judgment
A close match can be irrelevant or misleading, so users should be able to inspect the original file. Access controls also need to apply to search results. Running the model locally can avoid sending inputs to a remote inference service, but a developer still needs to check the rest of the application's network behaviour. Findbest has not installed or benchmarked this release; the technical specifications above come from Google. Browse our for other approaches to working with information.
Announcement date: 6 Oct 2026
What changed?
Google announced EmbeddingGemma 2 on October 6. It represents text, images and audio in a shared vector space.
Who is this relevant to?
Developers building search features and teams working with media archives.
What this means for your work
One query could retrieve material across different file types. Its usefulness depends on results in your own collection.
Limits of this report
No hands-on test. Memory figures come from Google and do not describe the total footprint of a complete application.
Read next
AI research: from answer to reliable source
A compact workflow for checking claims transparently.
Introduce AI to a small team: run a pilot before adding subscriptions
Use real tasks, a simple evaluation sheet and a clear decision to find out whether an AI tool helps your team.
Check AI answers: turn source links into supported claims
A source link is not enough. Check what it actually supports and whether the context matches.
Was this article helpful?
Your feedback helps us improve our articles.
Votes are counted per language version. Repeat voting is limited; totals do not necessarily represent distinct people. Privacy